

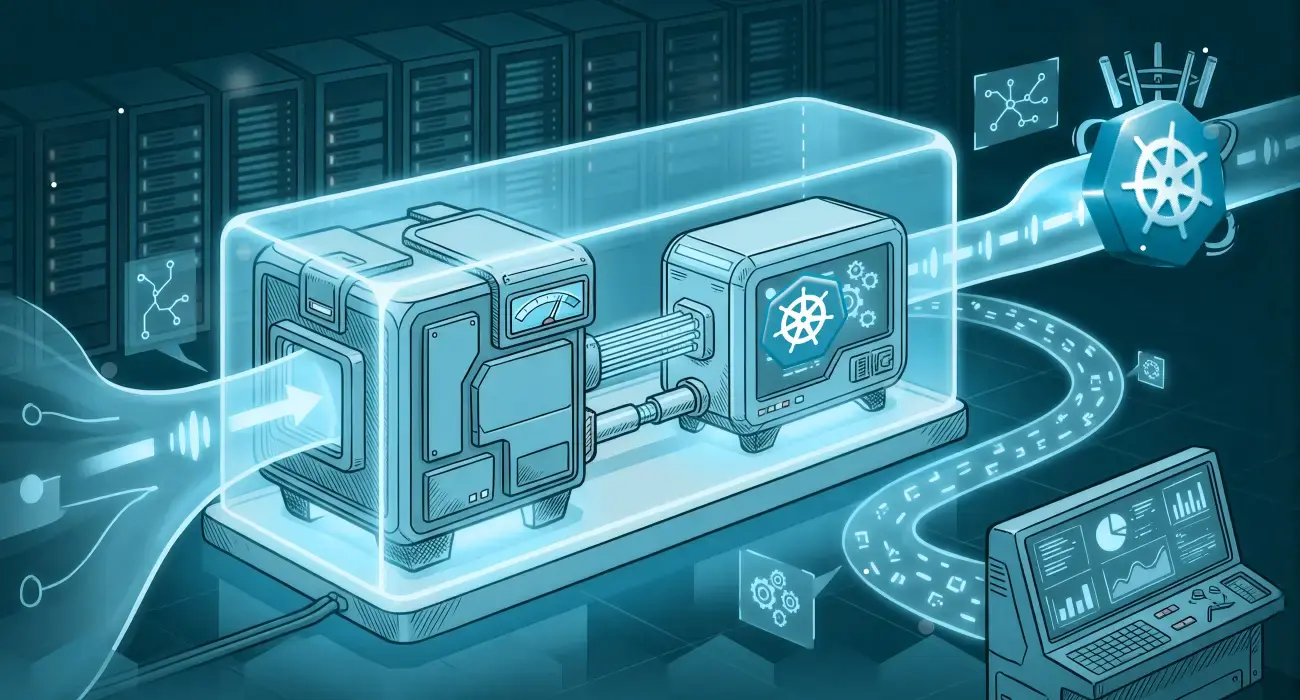
It shares the Pod’s network and lifecycle. This article covers how sidecars work, what changed with native sidecar support in Kubernetes v1.33, and when a sidecar is the wrong choice. By the end, you’ll be able to pick between a sidecar, a DaemonSet, or a sidecarless mesh for your workload.
The trade-off is simple: sidecars give you per-Pod isolation, but that isolation costs resources. Every sidecar adds its own CPU and memory request. Multiply that by hundreds of replicas and the cost adds up fast. That’s why native sidecar support exists, and why some service meshes now skip sidecars entirely.
Key Takeaways
- A sidecar shares its Pod’s network (localhost) and lifecycle with the main container, but runs as its own process with its own image and resource limits.
- Kubernetes v1.28 added native sidecar support: initContainers with restartPolicy: Always. It became stable in v1.33 (April 2025) and fixed job-completion and startup-order bugs from the old approach.
- Service mesh proxies (Envoy in Istio, Linkerd’s proxy) are the most common sidecar in production. They handle mTLS, retries, and telemetry without touching application code.
- Sidecars cost real money at scale. A proxy’s resource request is multiplied by every replica which is why Istio’s ambient mode moved proxies out to shared, node-level components instead.
- Not every job needs a sidecar. Node-wide concerns like host metrics fit a DaemonSet better; per-Pod concerns fit a sidecar better.
- The right choice comes down to one question: is this concern per-Pod or per-node?
What Is a Sidecar Container in Kubernetes?
A sidecar container is a helper container that runs next to your main application container, inside the same Pod. Because containers in a Kubernetes Pod share the same network namespace, they talk over localhost, with no DNS lookup and no network hop in between. The name comes from a motorcycle sidecar: a smaller unit attached to the main vehicle, along for the ride, doing its own job.
The pattern exists so you can separate side tasks logging, proxying, syncing config from your actual application logic. Instead of building a log shipper into your app, you run it as a second container that reads from a shared volume or watches network traffic.
Kubernetes doesn’t have a “Sidecar” object. It’s a pattern, not a resource type. You build one by adding a second entry to .spec.containers, or since v1.28 a flagged entry in .spec.initContainers. If you want the wider picture before adding per-Pod agents, Middleware’s Kubernetes monitoring guide covers what to track across a cluster first.
How the Sidecar Pattern Actually Works
Two things make sidecars work: shared networking and shared lifecycle.
Shared network
All containers in a Pod share one IP address and one set of ports. A sidecar proxy can bind to localhost:15001 and catch traffic meant for the app on localhost:8080, with no DNS step in between. This is what lets a service mesh proxy sit quietly in the request path.
Shared lifecycle (and its problems)
A sidecar runs alongside the main container in the same Pod, sharing its network and volumes. In the old model, before native sidecar support, every container in .spec.containers was treated the same way. Kubernetes had no idea that one container should start first, or stay running a little longer than the others. That caused two common problems:
- Jobs never finish. A Job with a sidecar (say, an Istio proxy) never completes, because the sidecar keeps running after the main container exits, and Kubernetes waits for every container to stop.
- No startup order. The app and its sidecar start at the same time. If the app needs its proxy ready first, its first few requests can fail.
Native sidecar support fixes both. Kubernetes 1.28 added a restartPolicy field to init containers, turned on through the SidecarContainers feature gate. The field is optional, and the only valid value is Always. Once set, a restartable init container won’t hold up Pod termination once the main containers exit. The official Kubernetes announcement covers the full details, including how it interacts with Jobs.
apiVersion: v1
kind: Pod
metadata:
  name: sidecar-example
spec:
  initContainers:
    - name: sidecar-proxy
      image: envoyproxy/envoy.22.0
      restartPolicy: Always   # marks this as a native sidecar
  containers:
    - name: main-app
      image: my-app
Native sidecars start before the main containers, keep running for the whole Pod lifecycle, and shut down on their own once the regular containers exit. The feature went from alpha in 1.28, to beta (on by default) in 1.29, to stable in Kubernetes 1.33, released April 2025.
Sidecar vs. DaemonSet vs. Sidecarless Mesh: A Comparison
Before going deeper, here’s how the three main approaches compare. If you’re setting any of these up, Middleware’s Kubernetes agent guide shows how to install a DaemonSet and a Deployment together with one Helm chart.
| Approach | Scope | Resource cost | Startup | Best fit |
|---|---|---|---|---|
| Sidecar (native, v1.28+) | Per-Pod | Scales with replica count | Starts before app, stops after | Different config per workload |
| DaemonSet | Per-node | Fixed per node | Runs on its own | Host metrics, log tailing |
| Sidecarless mesh (Istio ambient) | Per-node, shared | Shared across Pods on a node | Fully decoupled from the app | High Pod density, lower cost |
The line that trips teams up is resource cost. A DaemonSet costs one fixed amount per node, no matter how many Pods land there. A sidecar’s cost scales with replicas 200 replicas means 200 proxy containers, each pulling CPU and memory from the same node as the app.
Going Deeper: Four Sidecar Use Cases and Their Trade-offs
Service mesh proxies (Istio, Linkerd)
Service mesh sidecars are the most common sidecar at scale. Envoy runs as a sidecar in every application Pod and intercepts all network traffic inbound traffic passes through it before reaching the app, and outbound traffic passes through it before leaving the Pod. That lets the mesh apply mTLS, rate limiting, retries, and consistent telemetry across every service, with no app code changes.
The proxy catches traffic using iptables rules set up when the Pod starts, so every request routes through Envoy first. The app never talks to the network directly.
The cost: in sidecar mode, every Pod gets full L4 and L7 capability, whether it uses it or not. That Envoy container’s CPU and memory use is multiplied across every Pod in the mesh.
Verdict: Sidecar-mode service mesh works well when every workload needs mTLS and consistent observability, and Pod density is moderate. At high Pod density, the multiplied cost becomes the main problem.
Logging and log-shipping agents
A sidecar can tail application log files from a shared emptyDir volume and forward them to a log backend. This keeps log shipping separate from your app’s own code, so a change in log format or destination doesn’t need an app redeploy.
initContainers:
  - name: log-shipper
    image: fluent/fluent-bit:3.1
    restartPolicy: Always
    volumeMounts:
      - name: logs
        mountPath: /var/log/app
The trade-off: if your app already writes to stdout, a DaemonSet log collector does the same job with one agent per node instead of one per Pod. That’s far cheaper at scale.
Takeaway: Use a logging sidecar only when your app writes to a file, not stdout, or needs per-Pod log changes. Otherwise, a DaemonSet is cheaper.
OpenTelemetry Collector as a sidecar
A sidecar Collector gives each service its own instance with its own config. This is required on platforms like AWS Fargate or Azure Container Apps, where DaemonSets aren’t an option, and it’s useful when services need different processing. When paired with a DaemonSet, the sidecar handles application telemetry while the DaemonSet handles node-level data on its own.
The usual order of preference in Kubernetes is Deployment, then DaemonSet, then sidecar. Sidecars carry more upkeep: every workload’s config can drift, and every version upgrade has to be rolled out Pod by Pod. The official OpenTelemetry Collector docs cover this trade-off in more depth.
Bottom line: Reach for a Collector sidecar only when DaemonSets aren’t supported, or a workload truly needs its own telemetry setup. It shouldn’t be your default.
Configuration and secret sync
A sidecar can poll a secrets manager or config source and write updates to a shared volume a common job for tools like git-sync or Vault Agent. The main app just reads a local file that stays up to date, with no idea where the data actually comes from.
Watch for this failure mode: if the sidecar crashes quietly and there’s no health check tied to config freshness, the Pod keeps serving stale config with no visible error.
Takeaway: Pair any config-sync sidecar with a readiness or liveness probe that checks the config file’s age, not just whether the process is still running.
Deciding: Sidecar, DaemonSet, or Sidecarless?
Ask three questions, in order:
- Is this per-Pod or per-node? mTLS and per-service config are per-Pod. Host metrics and log tailing are per-node.
- Does it need app-specific config? A generic log tail doesn’t. A proxy with per-service routing rules does.
- Can the app handle sharing resources? A sidecar competes with the app for the same node’s CPU and memory. If the app is already tight on resources, that competition causes throttling under load.
Some concrete scenarios:
- A payment API that needs mTLS on every call, with per-route retry rules a sidecar proxy is the right call. The per-Pod config is the whole point.
- 3,000 stateless worker Pods that just need CPU, memory, and log data a DaemonSet is far cheaper. A sidecar here means 3,000 duplicate processes doing the same job.
- A serverless platform on AWS Fargate with no node access a sidecar is your only option, since DaemonSets aren’t available on platforms like Fargate.
- A cluster moving off Istio sidecars to cut memory overhead at high Pod density ambient mode’s ztunnel shifts the proxy to a shared, per-node component, trading some isolation for lower total cost.
Whatever you choose, watch for a sidecar quietly eating more memory than expected and starving the main container. Middleware’s guide on diagnosing abnormal Kubernetes workload behavior covers tracing that kind of resource conflict back to its cause.
Bridging the Gap: Why Sidecar-Heavy Clusters Need Correlated Observability
Sidecars solve an architecture problem, but they create a monitoring one. Every sidecar is another process competing for the same Pod’s resources, and a slow response could come from the app, the proxy, or the node itself. Without connected data, engineers end up checking kubectl top pod, proxy stats, and app logs separately to find the bottleneck. That’s exactly the manual work that correlated logs, metrics, and traces are meant to remove, so the cause is found automatically instead of pieced together by hand.
This kind of per-Pod resource tracking matters most under real load. Generation Esports, an EdTech platform serving over 200,000 students, needed clear visibility into its Kubernetes resource use during a cloud migration. Middleware’s resource data helped the team fine-tune node provisioning and avoid over- or under-using capacity during their move from AWS to Google Cloud; as a result, they reported saving close to 50% on node costs.
Middleware’s Kubernetes agent installs as a DaemonSet (node-level metrics) and a Deployment (cluster-wide data) with one Helm command. That gives you the node view sidecars can’t provide, alongside per-Pod detail, without building a third telemetry pipeline on top of your mesh’s own proxies. If you’re chasing a specific failure instead, our guide on diagnosing OOMKilled errors covers the memory side of sidecar resource conflicts directly.
Wrapping Up
The sidecar pattern trades resource cost for per-Pod control. Native sidecar support in Kubernetes v1.33 fixed the lifecycle bugs that made that trade-off riskier than it needed to be. Use sidecars for genuinely per-Pod jobs, like mesh proxies or config sync. Reach for a DaemonSet or a sidecarless mesh when the job is really per-node, and the cost of multiplying it by every replica stops making sense.
FAQs
Does every microservice need a sidecar?
No. Sidecars fit per-Pod jobs like service mesh proxies or config sync. Node-wide jobs like host metrics or basic log tailing are cheaper and simpler as a DaemonSet one agent per node instead of one per Pod.
What changed with native sidecar support in Kubernetes?
Native sidecars, stable since v1.33, are initContainers with restartPolicy: Always. They start before the main containers, run for the Pod’s whole life, and shut down on their own once the main containers exit. This fixed the job-completion hangs and startup-order issues the old approach had.
Do sidecars raise my cluster's costs?
Yes, in proportion to replica count. Each sidecar has its own CPU and memory request, multiplied by every Pod that runs it. A mesh proxy across 500 replicas adds 500 times the cost of a single sidecar to your cluster’s total footprint.
Is Istio's ambient mode a replacement for sidecars?
Not fully. Sidecars still matter for many cases, especially when a service needs config that’s more specific than a shared, per-account policy. Ambient mode is a good fit when the per-Pod proxy cost outweighs that need for detail.
Can I use sidecars on serverless platforms like Fargate?
Yes and sometimes it’s your only choice. Sidecar agents are required on managed platforms like AWS Fargate or Azure Container Apps, since DaemonSets aren’t available there.